NotifyHub: One Feed for Every Deadline That Matters
One Feed for Every Deadline That Matters
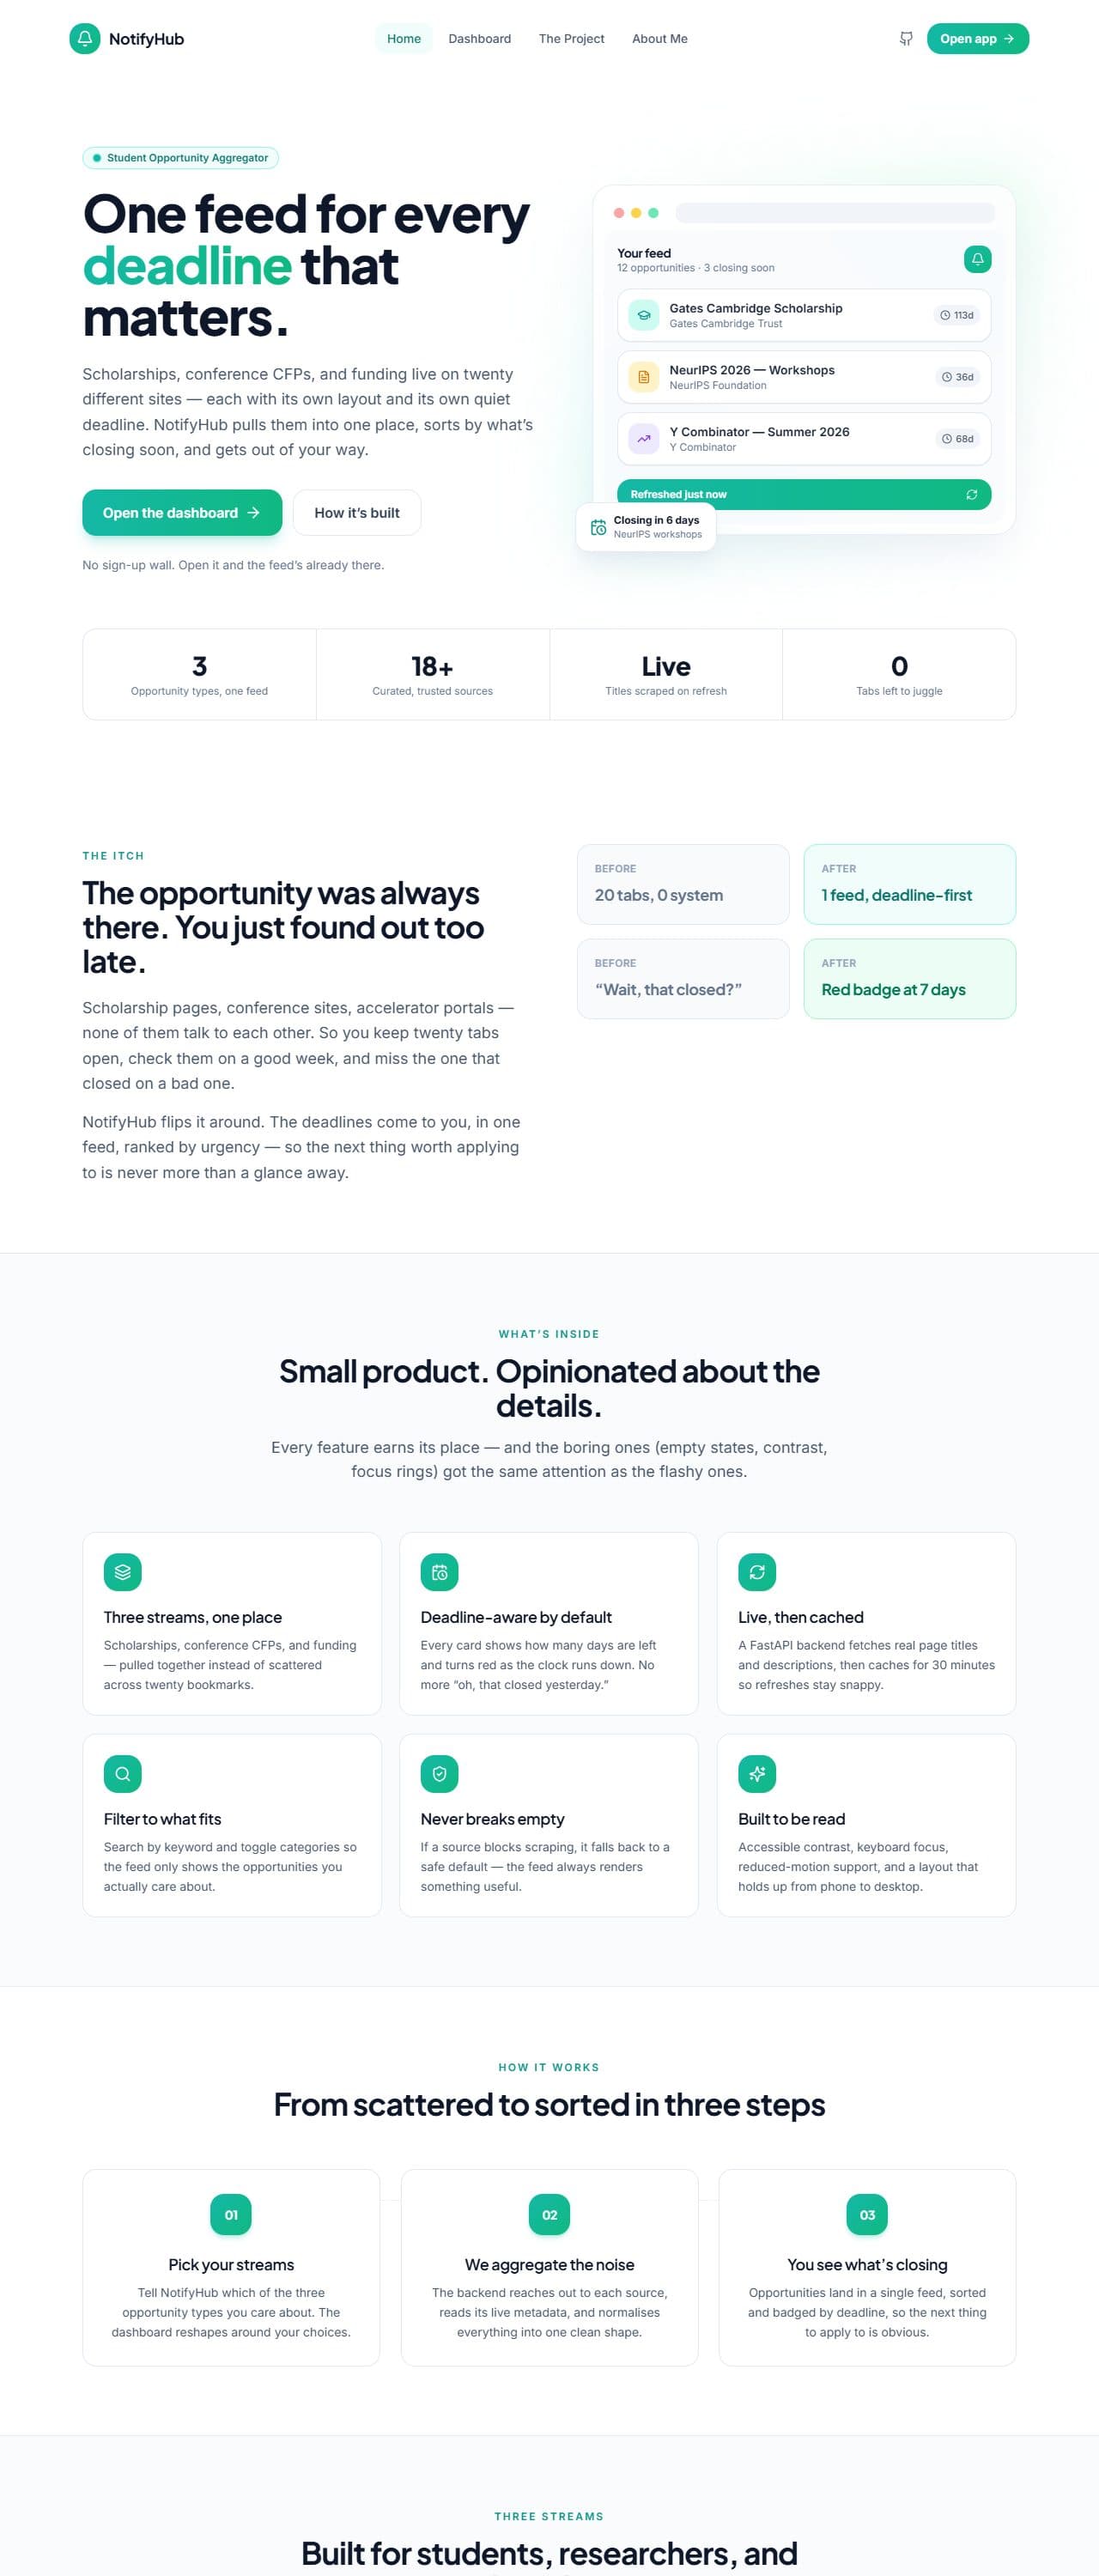
Scholarships, conference calls for papers and funding live on twenty different sites, each with its own deadline. NotifyHub pulls them into one feed sorted by what closes soonest. I built it after missing a CFP by two days.
- Year
- Sep 2025
- Timeline
- 5 weeks
- Type
- Web App
- Status
- Live
12 sources
Scraped concurrently and cached for 30 minutes. If a source blocks the scraper, or the backend is down entirely, the feed still renders from bundled data.
Overview
I missed a Call-for-Papers deadline by two days because it lived on a site I forgot existed. The information was public the whole time, and I had no system to catch it. NotifyHub is that system: scholarships, CFPs and funding normalised into one shape and ranked by urgency, with every card showing days remaining and turning red inside the 7-day window.
The hard parts
- 01
Twelve blocking HTTP scrapes in series made every refresh crawl.
- 02
Refreshing on every request hammered the source sites.
- 03
Real sites push back: they block user-agents, omit meta tags and mangle encodings.
- 04
A deployed site calling a localhost backend fills the production console with errors.
The approach
There are two loosely coupled halves that each run on their own: a React SPA that ships with a curated dataset and renders standalone, and a FastAPI backend that scrapes real page titles and descriptions. Each blocking scrape is pushed onto a worker thread and the batch is awaited concurrently, and a 30-minute in-memory cache means the fan-out happens at most twice an hour. Every fetch is wrapped so a failure falls back to seed values instead of failing the response. The frontend only calls the API when it makes sense (never a localhost backend from a deployed host), then enriches live results with deadlines by id.
Outcome
The Vercel deploy looks complete with no backend, and a local run upgrades itself as soon as the backend is alive. It does what I built it for: I no longer miss a deadline because it lived on a site I forgot existed.
What I'd do differently
The in-memory cache doesn't survive across serverless instances, and Redis or Vercel KV would fix that. Regex HTML parsing works for now, but a real parser would let me pull structured deadlines from the sites that expose them, instead of taking them from the bundled data.
Stack
Like what you see?
Let's build the next one.
Hiring, or have a problem that needs this kind of engineering? I read every message myself.